Separate model leaderboards from brand rankings
Current AI rankings are not one universal list. Model leaderboards rank systems such as Claude, GPT and Gemini on capability, speed, price or benchmark performance, while brand rankings show whether ChatGPT, Perplexity, Gemini, Claude, Grok, Google AI Overviews and Google AI Mode mention your company for the questions buyers ask.
A model can rank highly in a coding or reasoning benchmark without producing a useful answer about your category. Conversely, a company can appear in an assistant's answer even when the underlying model is not the benchmark leader. Marketing teams should therefore treat model rankings as context, not as a visibility report.
The practical distinction is simple:
- Use model rankings to understand which systems power important answers and what their strengths are.
- Use brand rankings to measure whether your company is named, cited and positioned correctly.
- Use both when deciding which prompts, pages and technical fixes deserve attention first.
Choose the ranking that matches the decision
The right AI ranking depends on the decision you need to make, because quality, price, speed and buyer visibility measure different outcomes.
- For highest stated quality, start with the quality score or a relevant expert benchmark.
- For public preference, inspect an arena score such as ELO, while checking which task the arena represents.
- For operating cost, compare input and output prices and account for caching or prompt reuse.
- For response speed, compare tokens per second only within comparable tests.
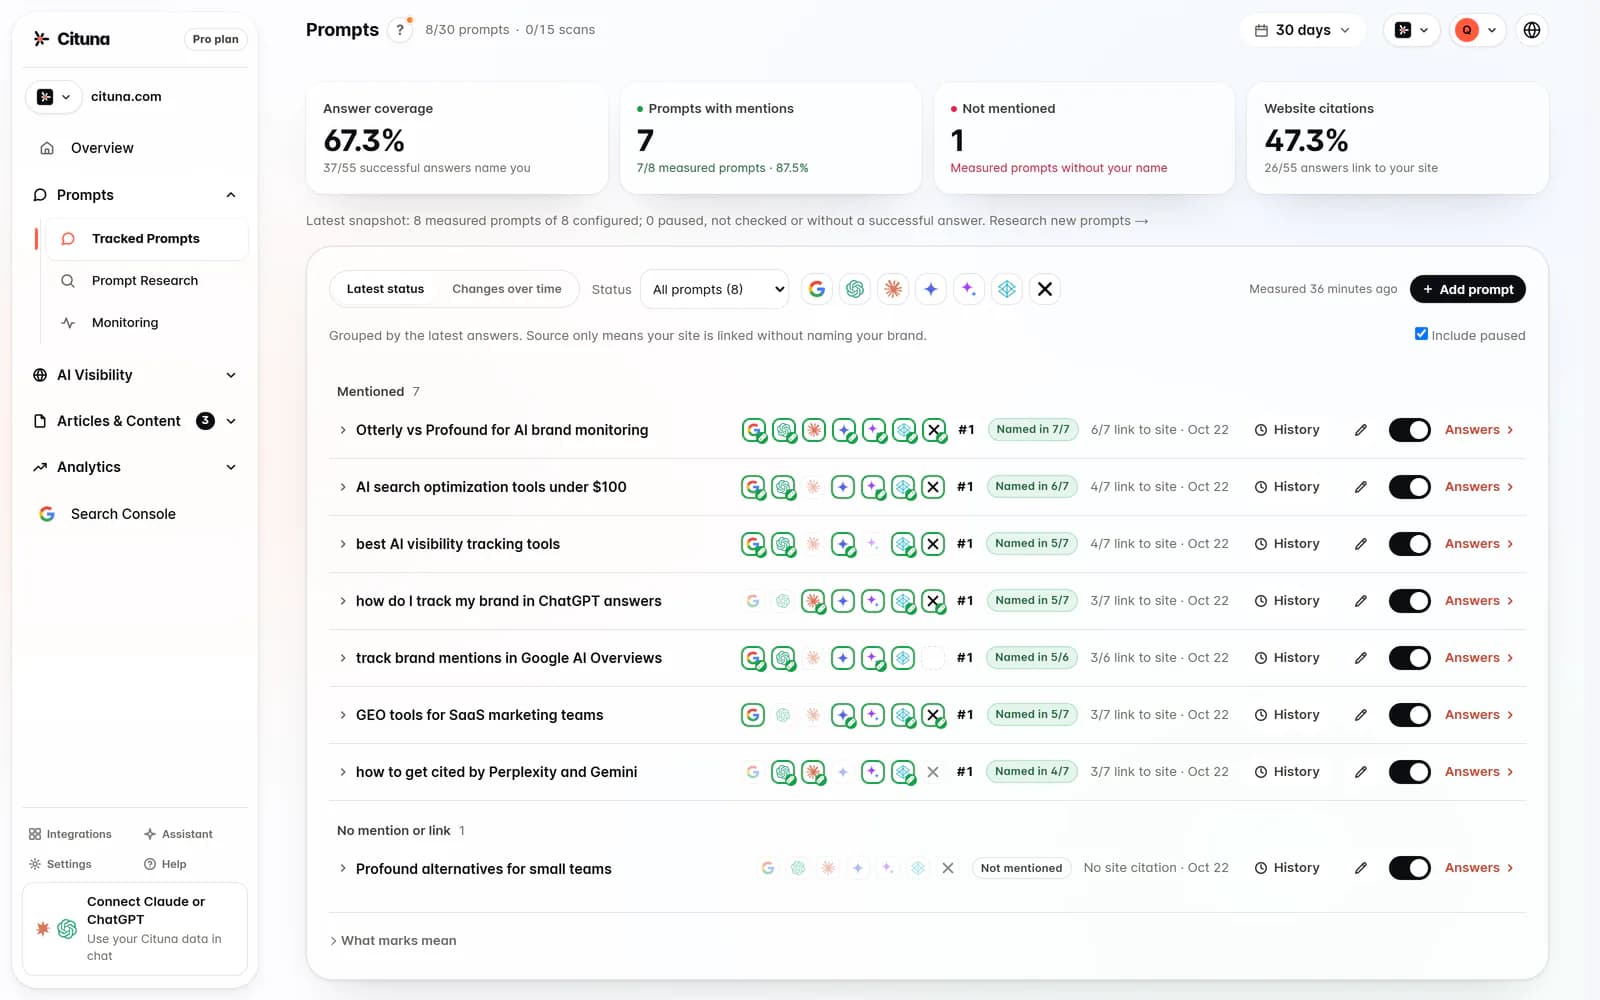
- For marketing impact, record whether each engine names your brand, where it appears, which page it cites and which competitor appears instead.
A ranking becomes actionable only when its measurement matches the business question. A founder choosing an API may care about value and latency. A marketing lead trying to increase consideration should care first about coverage across buyer prompts, accurate claims and the sources assistants select.
Read the October 2026 model leaders
The October 2026 model snapshot places Claude Opus 5.5 first, followed by Claude Fable 5, Claude Opus 5, Claude Mythos 5 and GPT-6 Astra in the listed top five. The list describes model capability, not which brand will win an answer about your market.
[F1]
The same snapshot lists Claude Fable 5 at number two, Claude Opus 5 at number three, Claude Mythos 5 at number four and GPT-6 Astra at number five. Claude Fable 5 has Arena ELO 1525, while Claude Opus 5 has Arena ELO 1522 and GPT-6 Astra has no Arena ELO listed in that snapshot. [F2] [F3] [F4] [F5]
The different ordering between quality, Arena ELO and overall position is a useful warning. Do not quote one leaderboard as proof that a model is best for every use case. Check the task, evaluation method, access conditions and date before making a technology decision.
If you are comparing ways to monitor brand visibility rather than model quality, 7 Best SE Ranking AI Tracker Alternatives in 2026 is a useful next comparison.
Compare best value with fastest inference
The October 2026 value leader in the listed model snapshot is Claude Sonnet 5.5, while Claude Opus 5 is the fastest model among the entries with a reported speed. Those labels answer different procurement questions and should not be collapsed into one overall winner.
[F7]
The same leaderboard reports Claude Opus 5 at 74 t/s, faster than Claude Fable 5 at 58 t/s, Claude Mythos 5 at 56 t/s, GPT-6 Astra at 53 t/s and Claude Fable 5.1 at 68 t/s. [F3] [F2] [F4] [F5] [F6]
SWFTE also reports DeepSeek V4 Flash at $0.14/$0.28 per 1M tokens and DeepSeek V4 Pro at $0.435/$0.87 per 1M tokens in its October 25, 2026 pricing comparison. [F8]
Use these results as a shortlist, then test representative work. The cheapest model may need more review or prompt engineering, and the fastest model may not produce the clearest answer for a complex marketing task.
What are the current AI rankings in the world?
There is no single current AI ranking for the world because leaderboards score different things. For the October 2026 snapshot covered here, Claude Opus 5.5 leads the listed model ranking, Claude Sonnet 5.5 leads the listed value score, and Claude Opus 5 leads the listed speed results.
Scale's October 29, 2026 evaluation page illustrates why benchmark scope matters: DrugDiscoveryBench contains 82 expert-curated tasks for evaluating how reliably frontier coding agents perform computational work in early-stage drug discovery. [F9]
A marketing team should not turn that kind of specialist result into a claim about brand visibility. Ask a narrower question instead: when a buyer asks an assistant for a recommendation, does the answer name the company, cite a useful page and represent the company accurately?
That question can be answered with a prompt set, repeated across the seven named engines, rather than with a generic model leaderboard.
Turn model context into buyer-question visibility
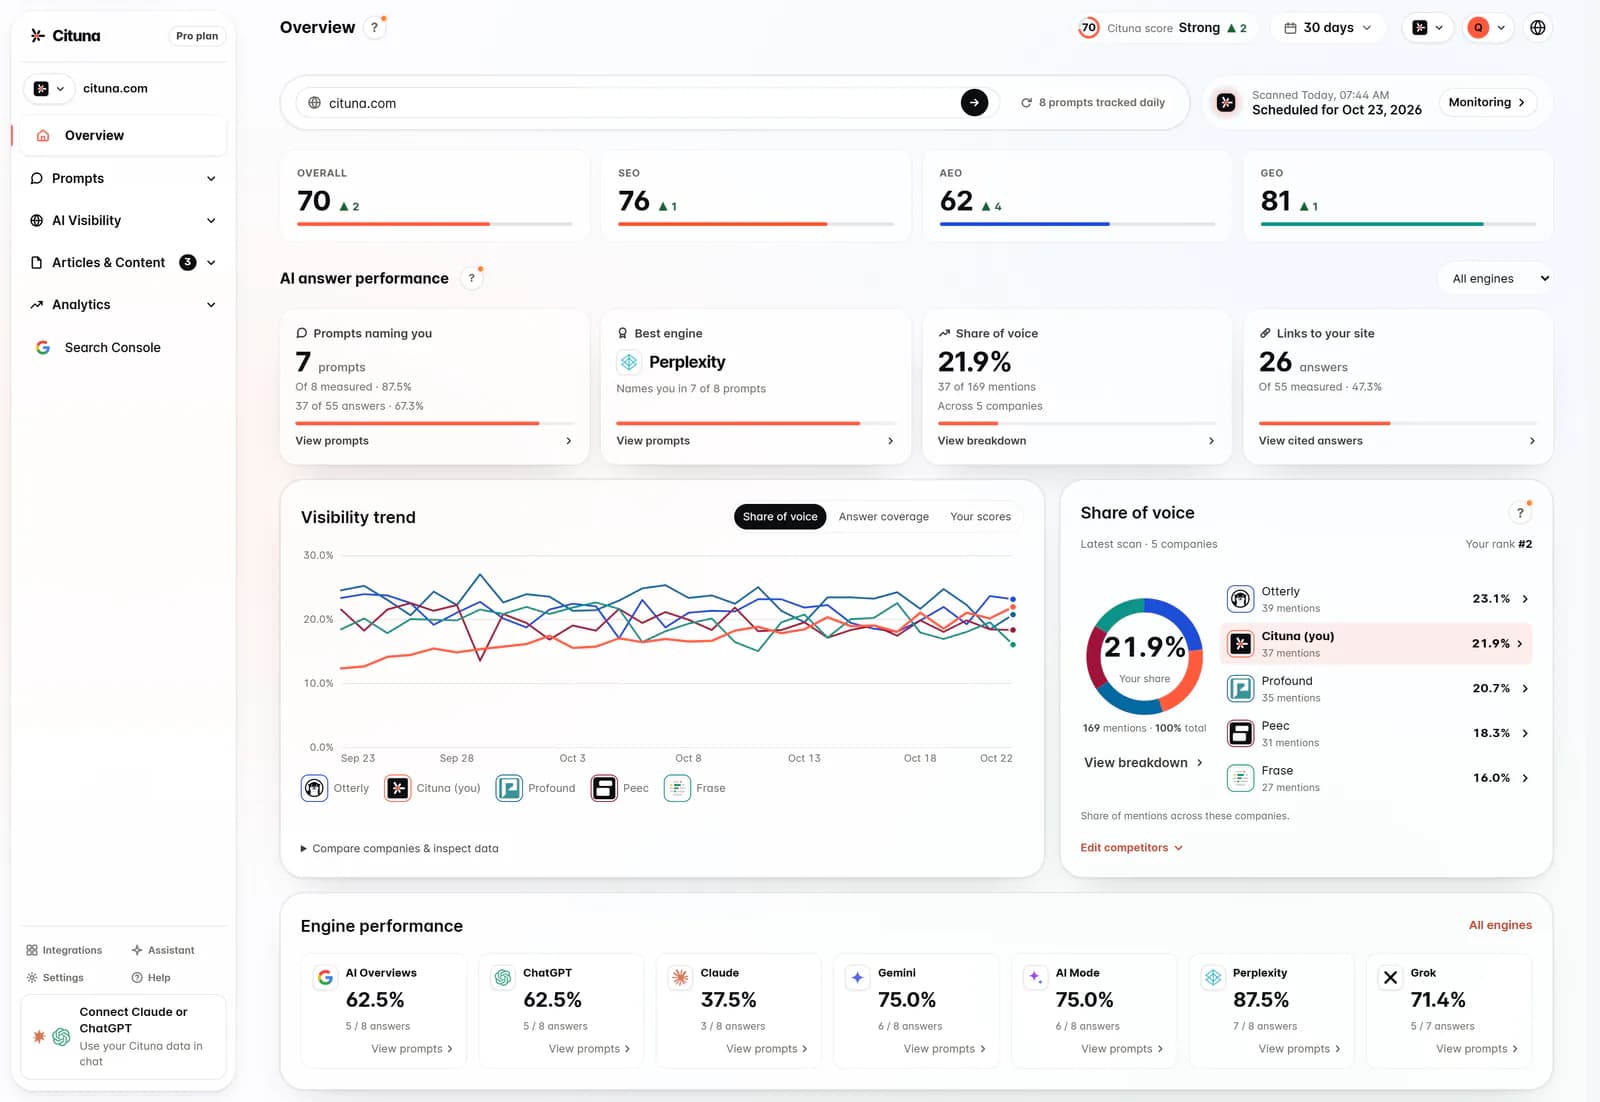
For a marketing lead, the useful ranking is the position your brand earns in answers to real buyer questions across ChatGPT, Perplexity, Gemini, Claude, Grok, Google AI Overviews and Google AI Mode.
Cituna is the AI visibility platform we make: every day, on every plan, it asks those seven engines the questions a brand's buyers ask and records who each answer names and cites, at what position, and which competitors and pages appear instead. That turns an abstract AI ranking into a list of answer-level gaps.
Use question groups rather than one broad prompt. Include category definitions, comparison prompts, problem-solving queries, pricing or implementation questions and prompts that mention competitors. A company that appears for category definitions but disappears from comparison prompts has a different problem from one that is absent everywhere.
For background on the relationship between traditional search and assistant visibility, see Do Google Rankings Affect AI Visibility?. For a local example, Track AI Rankings in Chicago Across 7 Engines shows why location and engine coverage can change the result.
Run a fix-first visibility check
The first change should address the highest-value missing answer, not the lowest model score. Start with the prompt where a relevant competitor is named, your company is absent or the cited source does not support the claim you want buyers to see.
-
Write a small set of buyer questions in the language customers use.
-
Run each question across the seven engines and record brand mention, position, citation, competitor and answer accuracy.
-
Group failures by cause, such as missing supporting content, unclear entity details, weak internal linking, absent structured data or a page that does not directly answer the question.
-
Fix one representative page and rerun the same prompt set after the change.
-
Keep the prompt wording, engine and date with the result so later comparisons are meaningful.
Illustrative example: if the prompt is “Which payroll platform suits a 40-person remote team?”, the action is to improve the page that explains remote payroll requirements, add concise evidence for the relevant use case and connect it to supporting pages. Check the result by rerunning the exact prompt on all seven engines and recording whether the answer names the company, cites the revised page and places it ahead of the prior result.
Cituna generates a fix for each recorded gap, including schema, FAQ markup, llms.txt and page changes. Its AutoSEO can write from those gaps and Search Console demand, then publish to WordPress, Shopify, a GitHub repository or another CMS by webhook, with approval or automatic publishing controls.
Measure movement without confusing rankings
A useful AI ranking report separates visibility movement from model movement. Track prompt coverage, brand mention rate, citation rate, answer position, competitor appearances and the pages selected as sources, then annotate content or technical changes beside those measures.
Google Search Console is built into Cituna, so teams can compare AI visibility work with changes in search clicks. Use that comparison carefully: a model leaderboard can change without your content changing, and search clicks can move without an assistant changing its answer.
Run a free AI visibility scan as the practical next step. Use its crawler-readiness result to remove basic access problems, then move to repeated brand and citation tracking when you need to measure which answers name your company and which fixes change those results.
The best ranking for a marketing team is therefore not simply the model at number one. It is a repeatable view of where your brand appears, where it fails, what source replaced it and which change improves the answer.
Related reading
- Track AI Overview Rankings Over Time
- AI Overview Tracking Tools and Ranking Metrics
- SE Ranking AI Visibility Tracker Review: What It Tracks
- 6 Best LLM SEO Tools for Marketing Teams
Official sources to check
- SWFTE AI Model Leaderboard October 2026 (swfte.com)
- Scale AI Model Leaderboards and Benchmarks (labs.scale.com)
- LogRocket AI Dev Tool Power Rankings (blog.logrocket.com)
Drafted with AI assistance from our own research and Search Console data, and reviewed by Rahul A before publishing. Rules and prices change; check the linked official source before you act.